
Experiments
-
Assume we want to use a vision-language model (VLM) to look at a given image and determine certain properties about it. Let’s say that, for the sake of the argument, we would like it to determine whether the image contains anything funny or not. As we all know, jokes are the most funny when you…
-
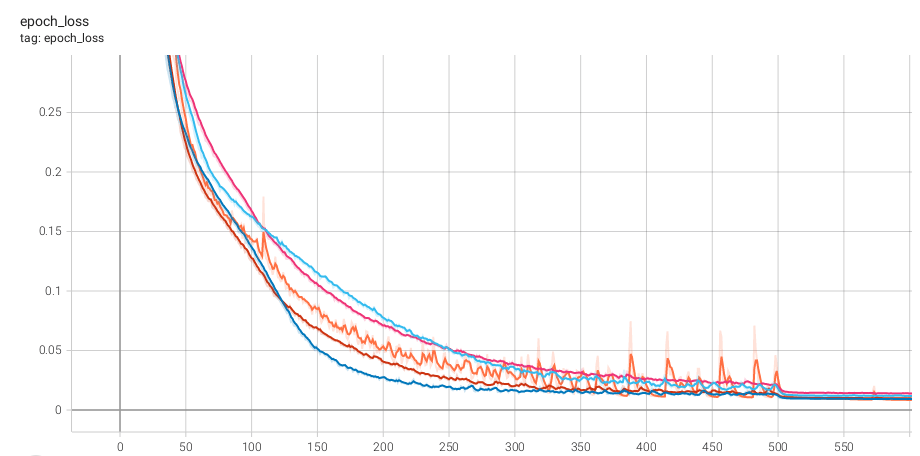
In my previous post about ThoughtNet, an attention-based neural architecture for variable-compute inference, I highlighted two limitations that I encountered with it: Slow and inconsistent convergence during training time Poor generalization on multiplication tasks, despite great performance on addition. While trying to solve the second problem, I stumbled across a surprising way to stabilize training…
-
The majority of today’s artificial neural network (ANN) architectures perform a constant amount of computation at inference time regardless of their inputs. This includes all recent GPT-style LLMs1 and other transformer-based architectures. Whether you ask an LLM to complete the series “1, 2, 3, …”, or you ask it to solve a complicated logic riddle,…

